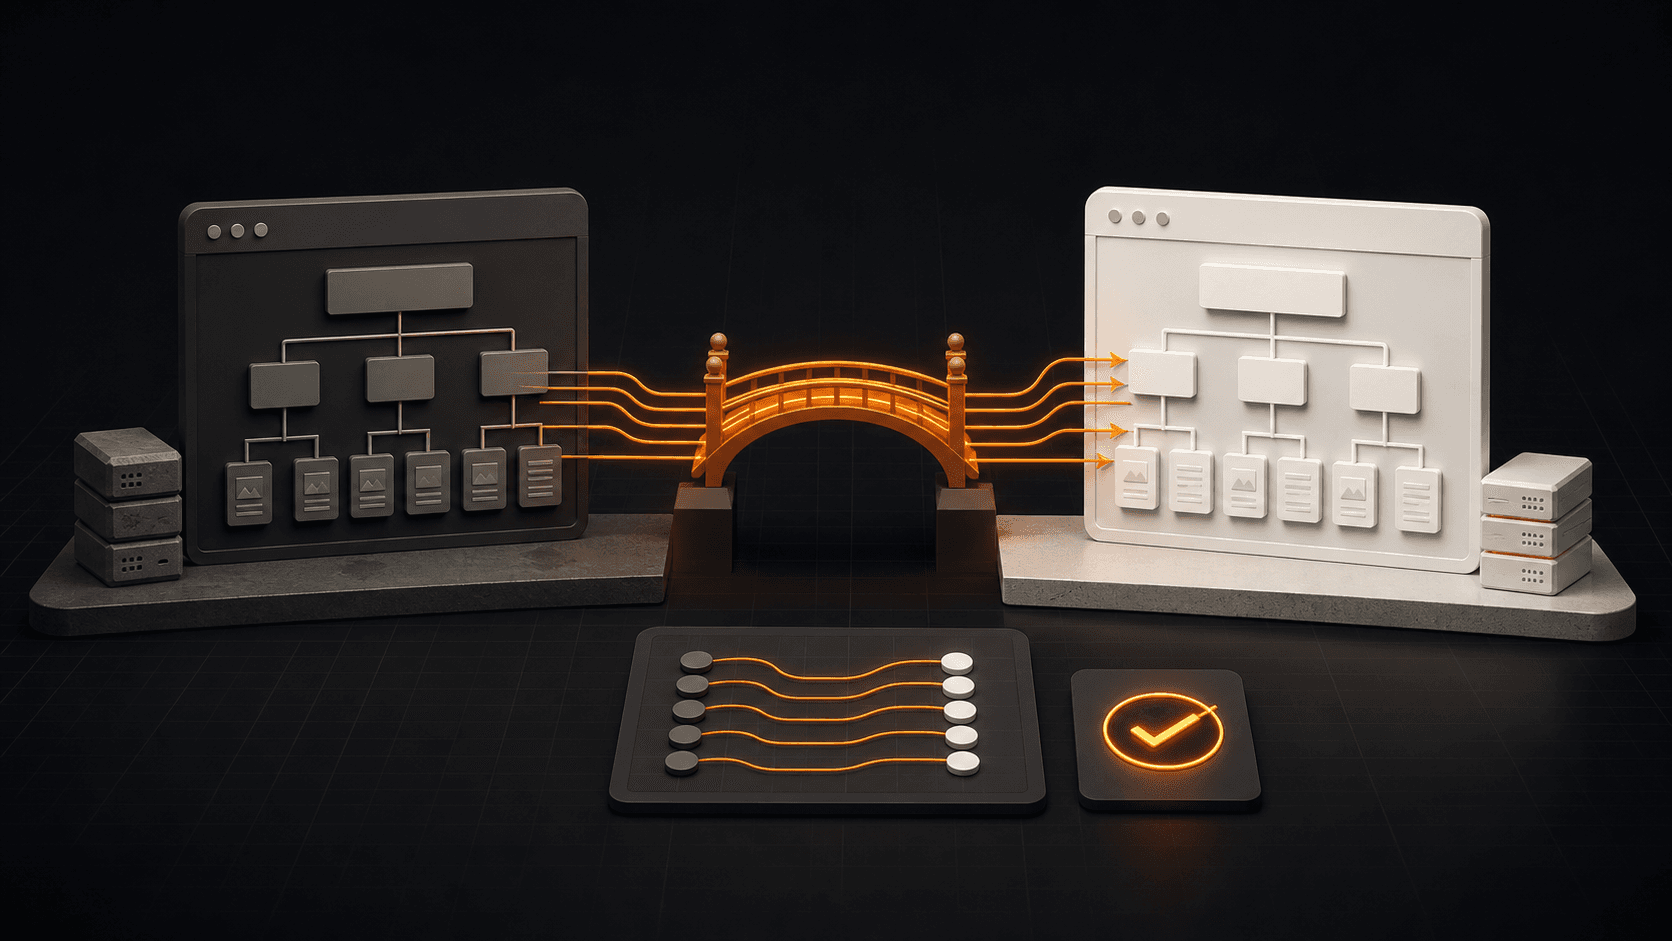
An SEO migration keeps your organic visibility intact while the domain, URLs, structure, CMS, design or technology changes underneath it.
You want search engines to get consistent signals, and you want to catch the mistakes fast after launch.
Most of the damage happens before launch day. The SEO gets invited to a finished site, nobody mapped the old URLs, and the new navigation no longer matches what people search for.
That is why I want to be in the project before the structure gets signed off. I've also been on the other side of this: my own site went from WordPress to a static site, and in January 2026 to Next.js. The checklist below is what I run on client projects and what I ran on my own.
When a change counts as an SEO migration
You need an SEO plan when you change:
- the domain or a subdomain
- HTTP to HTTPS
- the URL structure
- the information architecture and navigation
- the CMS or ecommerce platform
- server-side rendering to client-side rendering, or the other way round
- the design, if content gets removed with it
- language versions and
hreflang - several sites merging into one
- a separate mobile version
A purely visual change that leaves URLs, content and HTML alone can be low risk. In practice a redesign rarely stays that clean. Components, headings, internal links, rendering and tracking all tend to change with it, so it still needs a check.
The SEO's job in a migration
The SEO connects four things nobody else holds together: the history of the old site, search demand, the technical build and the plan for the new one.
A developer knows how to ship a redirect. I decide where each URL should go and how we prove it worked.
My part of the job:
- Find the URLs that carry organic value.
- Make sure the new architecture doesn't drop search intents that matter.
- Build or review the redirect map.
- Set the canonicals, robots rules, sitemap and
hreflang. - Check the server HTML and the rendered output.
- Write SEO acceptance tests for staging and production.
- Record the baseline and set up post-launch monitoring.
- Tell an expected wobble from a real bug.
If I only join after launch, I can still fix 404s and wrong canonicals. What I can't do without another redesign is bring back a deleted category, missing content or navigation nobody thought through.
Phase 1: inventory the old site
No single source is complete, so the inventory merges several:
- a crawl of the site
- the XML sitemap
- landing pages from Google Search Console and GA4
- URLs with external backlinks
- a CMS or database export
- landing pages from paid campaigns
- product feeds
- server logs, on a large site
- pages you know exist outside the navigation
For every URL, add the page type, status, organic traffic, conversions, links, canonical and the planned new target.
The inventory is where the keep, merge and remove decisions get made.
Phase 2: decide what to keep, merge or remove
Every old URL gets one of these outcomes:
- keep it unchanged
- move it to a new equivalent
- merge it into a more relevant page
- remove it with no replacement
- keep it temporarily during the transition
Not every 404 is a bug. A page with no value and no replacement can correctly return 404 or 410. The bug is removing a URL with traffic or backlinks and giving it nowhere relevant to go.
If a working URL can stay, that is often the safest option. A new CMS doesn't automatically need a new folder structure.
Phase 3: build the redirect map
The redirect map pairs every changed old URL with the closest relevant new target. Use permanent server-side redirects, status 301 or 308.
My rules:
- one old URL goes straight to the final target
- no chains, no loops
- don't send everything to the homepage
- keep the meaning and the intent of the page
- include parameter URLs and historical variants
- check letter case, trailing slashes and protocol
- keep the redirects long term
On sites with thousands of URLs I automate the first pass of the matching. The final review still has to look at intent. Two pages with similar titles aren't necessarily the same content.
A small example from my own site. On Next.js, permanent: true in next.config.ts returns a 308. When I audited the site on September 5, 2026, the old address /sluzby/seo-audit/ went through two 308 hops before it landed on /seo-audit. The obvious fix was a config change around trailing slashes. I tested it, it broke the old address with a 404, and I rolled it back. The two-hop chain stayed, accepted and written down, and shortening it is parked for a later routing change.
Phase 4: check staging
Staging should be blocked from indexing, but still reachable for the team and for the crawler you test with. Before launch I check:
- status codes for every template
- title, meta description and H1
- canonicals
- meta robots and
X-Robots-Tag - a production-ready robots.txt
- internal links that don't point at the staging host
- breadcrumbs and the main menu
- content in both the server HTML and the rendered HTML
- structured data
hreflangand the language mapping- Core Web Vitals and the main regression risks
- analytics and conversions
- a custom 404 page that returns a real 404
Whatever blocks staging must not ship to production. A noindex directive or a robots.txt rule left over from testing is one of the most common launch mistakes I see.
Phase 5: the launch checklist, with owners
Before launch, every item needs an owner and a way to verify it.
| Area | Check | Owner |
|---|---|---|
| DNS and domain | Final protocol, hostname, SSL | DevOps / dev |
| Redirects | A manual sample plus a full automated test of the map | Dev + SEO |
| Indexing | robots.txt, meta robots, canonical |
SEO + dev |
| Content | H1, body text, internal links, media | Content + SEO |
| Tracking | GA4, GSC, conversions, consent | Analytics |
| Sitemap | Only canonical URLs that return 200 | Dev + SEO |
| Monitoring | 404 and 5xx errors, logs, uptime | Dev |
The launch plan also needs rollback conditions. If payments break or most redirects fail, the team has to know who makes the call to roll back.
Phase 6: check the site right after launch
The first check happens within minutes and hours of going live.
Verify that:
- the homepage and representative URLs return 200
- old URLs return a single 301 or 308 to the right target
- production isn't blocked
- canonicals use the final domain
- internal links don't point at staging or run through redirects
- the sitemap is live and correct
- analytics records visits and conversions
- there are no mass 404s or 5xx errors
- Google can render the main content
My quickest check runs in the terminal. curl -I on an old URL shows the status code and the Location header in one line, and curl -IL follows the whole chain. That is also how I phrase acceptance criteria for developers: a command, an expected status code, an expected target.
If the domain changed, add the new property in Google Search Console, submit the sitemap and use the Change of Address tool when it fits the type of move.
Phase 7: monitor organic performance
After launch, watch technical errors daily and the organic trend over longer windows.
Segment the data by:
- page type
- old and new URL
- branded and non-branded queries
- country and device
- folder and language
- index status and canonical
- conversions
Total traffic can hide a problem in one section that makes the money. Normal seasonality can also look like a migration bug.
Compare against the pre-launch baseline and log the date of every fix. On a large site, also watch the server logs and how fast Google moves over to the new URLs.
One lesson from my own site: I don't treat the first few months of Search Console data after a migration as a stable baseline. Google is still reshuffling signals. Rewriting titles to chase CTR in that window mostly reacts to noise.
What to do when traffic drops after a migration
First, size the problem. Did the whole site drop, one page type, one country, or a single topic cluster?
Then check in this order:
- HTTP status codes, availability and rendering.
- Robots rules,
noindex, canonicals andhreflang. - The redirect map and redirect chains.
- Lost content and internal links.
- Changes to titles, H1s and page intent.
- The sitemap and the index status in GSC.
- Analytics and any change in tracking.
- Seasonality, Google updates and competitors.
Don't blindly restore the old title or copy until you know which template and which queries changed. Diagnosis works from a hypothesis and evidence.
The migration mistakes I see most
- SEO gets invited after the site is finished
- every URL changes for no reason
- old URLs redirect to the homepage
- redirects form chains
- a staging
noindexsurvives into production - important copy and internal links disappear
- the canonical points at the old domain
- the sitemap lists redirects and 404s
- analytics gets tested after launch
- monitoring only covers total traffic
- redirects get removed after a few weeks
Getting help with a migration
The effort depends on site size, the number of templates and URLs, whether the technology changes, how many languages you run and how involved your dev team is.
A smaller redesign that keeps its URLs may need a few consultation sessions. An ecommerce replatform or a domain move is its own project.
I usually start by scoping it in an SEO consultation. For a more complex migration, technical SEO or an SEO audit follows, with the inventory, the redirect map, acceptance tests and the post-launch check. If the new site runs on React or Next.js, JavaScript SEO covers the rendering side.